Release · October 20, 2026 · Nuva Lab × FastVideo

FastH3-Omni: Your Open Source “Unlimited Seedance” is here

FastH3-Omni is out. Open Weight. Open Source. You will love it.

TL;DR

  • Open sourceThe open-weight, accelerated version of MiniMax H3 is now open to everyone, with full omni reference input (image, video, and audio, like Seedance 2.5) and 5 to 15 second video with synchronized audio in one pass.
  • Built by Nuva Lab with FastVideoContinuing years of co-development. We ran it as an exclusive early-access partner during the preview, shipping to top performance ad agencies, animation studios, and entertainment companies.
  • Our missionDemocratizing and scaling up content creation, with a founding team deeply rooted in the open-source community.
  • 5.6–11.9× fasterLower end-to-end latency than MiniMax H3 on 8 NVIDIA GB200 GPUs, across 27 matched reference workloads measured by FastVideo.

What FastH3-Omni does with references

These three clips come from the FastVideo team's release gallery. The open FastH3-Omni model generates video and audio in one pass, and these clips have music without dialogue.

References
  • Video · 6 s
Output5 s video + audio

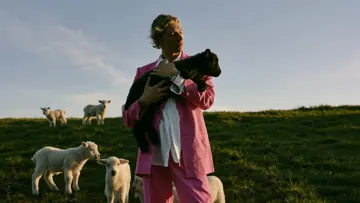
One 6-second video reference

A 6-second hillside video shows a man in a pink suit holding a black lamb. The prompt generates a quiet 5-second clip over music.

References
  • 9 photos
Output5.5 s excerpt of 15 s

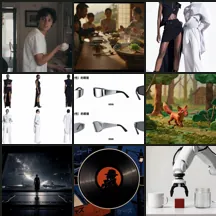
9 reference photos for a five-shot commercial

9 photos prompt a 15-second commercial that changes style each shot. In this 5.5-second excerpt, the fashion model and clay fox wear the same sunglasses.

References
  • Video · 2 s
Output5 s video + audio

Only the first 2 seconds as reference

The input uses only the first 2 seconds of the first video. The model generates a 5-second clip of the same man and lamb.

Outputs use seed 0, 8 transformer forward passes, and FastVideo's 36-layer NVFP4 VAE decoder. With the original VAE on 8 NVIDIA GB200 GPUs, FastVideo measured 5.6 to 11.9× lower end-to-end latency than MiniMax H3 with 50 denoising steps across 27 matched gallery samples.

What’s New in FastH3-Omni

FastH3-Omni matches MiniMax H3's full omni reference mode and takes the same mix of image, video, and audio inputs as Seedance 2.5, generating a 5 to 15 second video at 24 fps with synchronized audio in one pass.

We trained FastH3-Omni with a lot more high-quality data and trajectory-based distillation using a joint distribution-matching loss. We also built hardware-friendly sparse attention kernels and calibrated NVFP4 components for Blackwell and consumer GPUs. Speed versus the default MiniMax H3 omni reference: 5.6–11.9× lower end-to-end latency on 8 NVIDIA GB200 GPUs across 27 matched reference workloads, measured by FastVideo.

Built by Nuva Lab and FastVideo

Democratizing and scaling up content creation has been the centerpiece of Nuva Lab's mission since our inception, with our founding team deeply rooted in the open-source community as the backbone of modern AI development.

Nuva Lab built FastH3-Omni on the MiniMax H3 base model together with FastVideo at Hao AI Lab at UC San Diego. FastVideo has been Nuva Lab's core research partner for two years, across FastVideo v1 training stack design and battle-testing, from Wan to H3, and many more in the future.

We've worked closely together on FastH3 since the ideation and experiment design phase, across omni reference dataset definition and curation, training experiments, and inference optimization, through the preview text-to-visual-audio launches of FastH3 v1 and v2, and finally leading up to our main target, the FastH3-Omni release.

  1. Ideation and experiment design
  2. Omni reference dataset definition and curation
  3. Training experiments
  4. Inference optimization
  5. FastH3 v1 preview
  6. FastH3 v2 preview
  7. FastH3-Omni releaseOpen source · Oct 20, 2026

Thanks a lot to our collaborator from Reactor for the additional B300 compute!

MiniMax H3 is the first open-weight omni reference video generation model in the world, with unified understanding and generation and unified modalities with single-stream full attention all in one piece. It is an invaluable asset the community has long waited for, making many use cases, creative ideas, and business models possible.

It’s the DeepSeek R1 moment for content generation.

We are proud to open-source it to everyone for the democratization of content creation at scale, and we hope you love it.

Open Source Version: Run it yourself on consumer hardware

You can try and deploy FastH3-Omni on your own consumer devices. It runs on NVIDIA RTX GPUs, DGX Spark, and Apple Silicon (MLX). The FastVideo release post has the full technical breakdown.

Weights: Hugging Face · Release post: FastVideo blog · Code and training: FastVideo on GitHub

VRAM and RAM by GPU: MiniMax H3 VRAM and GPU requirements.

The Production Version: Nuva Lab

For enterprises generating content at scale, we run a production version of FastH3-Omni trained on more high-quality data with further optimization. It performs even better than the open release on quality, speed, and reliability, and a few top ad agencies, animation studios, IP holders, and entertainment companies already run it in production with us.

Demand scale

Tesla + FSD

A dedicated deployment that generates unlimited video clips, plus an autonomous agentic FSD system that self-improves based on your feedback and business data.

Demand customization and quality

Deep customization on your data

We work with the pickiest IP holders in the world, from project inception, dataset curation, and model architecture design to workflow integration and production.

raw clipscurated setIn-housedatasetOmnireferencecurationData-calibratedoptimizationNiche stylematch

01Customization

Data quality and style calibration

We built a large, high-quality in-house dataset over the years and defined omni reference dataset curation. Data-calibrated optimization improves model quality further to match your art style and content niche.

open weightsproduction1234Open weightsExtratrainingstagesTrajectory-baseddistillationDistribution-matchingloss

02Customization

Training expertise beyond open weights

We co-designed and battle-tested the FastVideo v1 training stack from Wan to H3. Production adds extra data, compute, and training stages on top of open weights, with trajectory-based distillation and a joint distribution-matching loss.

optimization stackthroughput ↑Sparse attentionCalibrated NVFP4 kernelsHigh-concurrency orchestrationGuaranteed throughput

03Scale

Full-host dedicated inference at scale

We run full-host dedicated deployments with hardware-friendly sparse attention, calibrated NVFP4 kernels, optimized networking, decoding, and high-concurrency orchestration. You get dedicated, guaranteed concurrency and throughput at the best throughput per dollar.

your datayour modelCharactersProductsVoicesBase modelYour modelProjectinceptionDatasetcurationModelarchitecturedesignCustomfine-tuningWorkflowintegration

04Customization

Your data, your custom model

Fine-tune deeply on your data, characters, products, and voices. We work with the pickiest IP holders from project inception, dataset curation, and architecture design to workflow integration and production. Data stays in your deployment.

WritepromptsPickreferencesRenderclipsCheck andretryLearn fromdata24/7CreativeAgentPreference dataBusiness datafeeds the loopWritepromptsPickreferencesRenderclipsCheck andretryLearn fromdata24/7CreativeAgentPreference dataBusiness datafeeds the loop

05Scale

Closed-loop creative and data agent

Your autonomous Creative Agent runs 24/7 while your team sleeps. It writes prompts, picks references, renders, retries, and checks clips, then self-improves from preference and business data across model output, concept experiments, and business decisions.

Here is how the open release and Nuva Lab production compare:

Open weightsFor consumer GPU experimentsNuva Lab productionFor production deployment at scale
Where it runsYour hardware (NVIDIA RTX GPUs, DGX Spark, Apple Silicon)Full-host dedicated deployment with Nuva Lab
ModelPublic FastH3-Omni open weightsProduction FastH3-Omni, custom fine-tuned on your characters, products, and voices
DataCurated omni reference datasetLarge in-house curated dataset plus your data to match your style and niche
QualityThe open FastH3-Omni checkpointExtra data, compute, and training stages, customizable on your in-house data
Long video5-15 s clips (keyframes and clip continuation)Native long video in latent space without stitching clips
Creative AgentNoFully autonomous and works while your team is sleeping
Improves over timeWhen you retrain itClosed loop on your preference and business data
Latency, throughput, and concurrencyLimited by your hardwareDedicated concurrency and throughput with optimized kernels, networking, decoding, and orchestration
Security and privacyStays on your hardwareStays in your deployment; zero data retention for enterprise data on dedicated deployments
FAQ

Questions

What is FastH3-Omni?

FastH3-Omni is our open-weight, accelerated version of MiniMax H3 with full omni reference input. It takes text, up to 9 reference images (up to 3 in realtime mode), up to 3 reference videos (2 to 15 seconds each, 15 seconds total), and up to 3 voice or music audio references (2 to 15 seconds each, used together with an image or video reference), up to 12 reference files total. It also takes first and last frame keyframes in the same request, supports clip continuation, and generates a 5 to 15 second video at 24 fps with synchronized audio in one pass.

Who built FastH3-Omni?

Nuva Lab built FastH3-Omni together with FastVideo at UC San Diego's Hao AI Lab, our core research partner for two years. We ran the model as an exclusive early-access partner during the preview before releasing the open weights and training code on October 20, 2026.

Where can I download it?

You can download the open weights and training code at huggingface.co/collections/FastVideo/fasth3-omni and read the technical release post at haoailab.com/blogs/fastvideo-omniref-update/. The model runs on NVIDIA RTX GPUs, DGX Spark, and Apple Silicon (MLX).

How fast is it compared with MiniMax H3?

Speed versus the default MiniMax H3 omni reference: 5.6–11.9× lower end-to-end latency on 8 NVIDIA GB200 GPUs across 27 matched reference workloads, measured by FastVideo. We reached this speed with trajectory-based distillation using a joint distribution-matching loss, hardware-friendly sparse attention kernels, and calibrated NVFP4 components for Blackwell and consumer GPUs.

How is the Nuva Lab production version different from the open release?

Our production version uses a larger curated dataset, extra training stages, and full-host kernel, networking, and decoding optimizations to beat the open release on quality, speed, and reliability. It adds native long video in latent space without stitching clips, a fully autonomous Creative Agent, dedicated concurrency and throughput with no shared queue, custom fine-tuning on your characters, products, and voices, a closed loop on your preference and business data, and zero data retention for enterprise data on dedicated deployments.

Sources and further reading

Read next

Run FastH3-Omni in production with Nuva Lab

If you run video production at an ad agency, animation studio, game company, or content team, we can set up a dedicated deployment for your workflow. Fill out the 1-minute form to talk with our team.

Work with Nuva Lab · 1 min